As members will be aware over the past couple of weeks we have been collating feedback and comments from you all on the RCUK's revised policy on open access. Many, many thanks to those members and Committee whom have contributed to the drafting of UKCoRR's response - which I can confirm has just been submitted to their communications officer. In the spirit of the openness that underlies everything UKCoRR does - the text of the communication follows. Naturally we'll share with you any and all response the Committee receives.
----
UKCoRR, on behalf of its membership, wishes to respond to the RCUK’s proposed policy on access to research outputs, given that it is an area that directly impacts on the activities of our 250+ members across the UK’s research establishments.
At the outset, UKCoRR would like to commend the RCUK for a very clear, positive and explicit statement. In particular the restriction of support for embargoes longer than 6 months post-publication (12 for AHRC and ESRC funded work). UKCoRR are also delighted to note the tone of the policy in favouring more Open Access friendly journals and publishers for RCUK funded research outputs.
There are, however, several issues, concerns and clarifications that our membership would like us to flag up for your attention and consideration.
Definition of Open Access
UKCoRR would query the definition of Open Access to scholarly publications as digital journal articles. "The Research Councils define Open Access to mean unrestricted, on-line access to peer reviewed and published scholarly research papers." [p2] and likewise your classification of books or monographs as “grey’ literature” [p3]. There are many other types of authoritative research output besides pdfs of journal articles, especially in arts and humanities research. It is our belief that the OA movement needs to lobby for access to all research outputs, and that there is a need to ensure that RCUK’s policy does not exclude this significant portion of the scholarly literature. The contents of our members’ Open Access repositories clearly demonstrate the richness, value and readership of such scholarly works.
Creative Commons
The CC licence is a potentially contentious issue [p2] and one that UKCoRR believes may create more problems than it solves.
The current model of Green OA (i.e. self-archiving in an IR) as opposed to Gold (i.e. author-institution pays), is predicated on a pragmatic negotiation of copyright with academic publishers and, along with high profile initiatives like SHERPA RoMEO, has encouraged growth of the number of RoMEO green journals which allow self archiving, and therefore in the potential number of OA papers that can be self-archived in repositories. UKCoRR is concerned that the new policy will potentially impact on this strategy, and on repositories which will have to assert CC-BY on relevant papers after a maximum embargo period of 6 months.
It is not clear what effect the policy may have on journals defined as ‘green’ by SHERPA RoMEO and on the application of embargoes. Journals may choose to become RCUK-compliant, to remain RoMEO green but not compliant, or to reject green and compliance altogether with individual publishers’ policy likely to be informed by the potential loss of revenue resulting from a universal 6 month embargo and by the extent to which other funders will follow RCUK's lead on CC-BY.
HE institutions are increasingly adopting policies on OA and self-archiving in their repositories and UKCoRR has some concerns that the policy should more explicitly consider implications to this Green route to Open Access
Limitation on Publication Destination
While UKCoRR acknowledges the value of this part of the policy, we note that it is likely to cause anxiety among academic stakeholders unless backed up by clear support mechanisms. If our members’ author stakeholders are made to feel more constrained on their choice of where to publish [p3] it could generate an adverse perception and consequent resistance towards the implementation of Open Access policies within their organisation; already an issue that many of our members encounter in the course of their work. However, we look forward with interest to the impact this may have on those publishers who to date have been reluctant to embrace more Open Access compliant author copyright licence agreements.
Impact on Publisher Policy
The policy would require a significant change in many publishers’ policies, and would limit the choice of journals to those that are recognised as compliant. Sources of funding for Open Access compliance will therefore become a more pressing issue across many institutions, where few currently have resources set aside to cope with such moves [p5]. We would encourage RCUK to be more proactive in ensuring that all researchers, especially PIs, and research administrators are made fully aware that this is part of the indirect costs allocated within the grant application and award. Clarity on RCUK’s stance in this regard would be especially welcomed by our membership.
Access to Data Outputs
The final paragraph in section 8 says "The underlying research materials do not necessarily have to be made Open Access" [p6]. While UKCoRR understands that mandating open data publication is out of the scope of this policy, we would welcome an approach that encourages this. There is an opportunity here to get more open data for use and reuse by the research community while respecting the normal provisos about commercial sensitivity, patient confidentiality etc.
Compliance Mechanisms
Our membership would also be interested in knowing more about how the “mechanisms to help ensure compliance” will operate [p6]. Given the time scales and workloads already placed upon our members, greater clarity in this regard and at the earliest opportunity will make such mechanisms more practicable for us to implement.
OA Fields and ROS
Given the timing of this, we would also query the lack of proper OA fields built in to the recently launched Research Outcomes System (ROS). There are fields for SHERPA/RoMEO data and preprint/postprint, but nothing to clarify if an OA version actually exists. While we are aware of discussions ongoing with the JISC that UKCoRR has also been party to, we would welcome this being highlighted in the policy.
Final Comments
Overall, as strong advocates of the cultural, economic and intellectual benefits of Open Access to the UK’s unique research outputs UKCoRR keenly supports this bold policy.
We welcome any opportunity to enter into a dialogue with the RCUK as to how this could be cascaded, both to our membership and our academic stakeholders.
Tuesday, 3 April 2012


Thursday, 22 March 2012
Using Google Analytics Statistics within DSpace
Thank you to Claire Knowles of Edinburgh University who provides this overview of how they have been able to display statistics from Google Analytics in DSpace.
----
In 2009 Edinburgh University
Digital Library adopted Google Analytics (GA) to track usage statistics within
the DSpace Repositories it supports on behalf of the Scottish Digital Library
Consortium (SDLC). The GA statistics
have proven much more reliable than the existing plugins available for DSpace
previously with which we experienced lost statistics and inflated pageviews
resulting from robots.
Unfortunately the GA statistics
for sites being tracked are only viewable via the GA dashboard for which users
require a Google account and managed permissions. This limits the visibility of statistics to a
few people at each institution.
Prompted by the presentation given by Graham Triggs (then working for
BioMed Central) at the Open Repositories Conference 2010, we decided to write
some code to make the Google Analytics statistics visible to all users of the
DSpace installations.
The work has been broken into
phases:
1. Capture of downloads in
DSpace by Google Analytics.
The basic GA tracking code within
DSpace is unable to capture the number of file downloads as these are not links
within pages. To address this we added
code to the two downloads on the item page to enable these download actions to
be measured. This captured all downloads
within Dspace but not those users coming directly from search engines to the
download file. To capture these
statistics we decided to reroute all users back through the item page. This
means that they now have two clicks instead of one to reach the download but it
enables us to capture these statistics and also raises the visibility of the
Repository to users. To reduce the
inconvenience to the users we moved the file downloads links on the item page
from the bottom to the top so that they do not have to scroll down to find the
download.
2. Adding page views to each
item page within DSpace
Secondly, we added the number of
page views within the last year to the item page. This was a proof of concept which showed that
we could connect to the Google Analytics API and pull back statistics into
DSpace. We decided to only include the
number of views for the past year to reduce any disparities between the the
number of pageviews between older and new items.
3. Making statistics viewable
within the DSpace web pages.
We decided to make the GA
statistics available at three levels: item, collection and repository as this
provides most of the statistics which are requested by users. Using the Query Explorer provided by Google
we were able to test and refine our queries before starting development. The pages were developed using the Google
Analytics java API, jQuery and the Google Chart tools to draw graphs and maps.


As we complete the rollout of
Google Analytics to all the SDLC partners we are starting to look to what other
statistics we would like to make available both from Google Analytics and also
possible exposing statistical information about DSpace using Google's chart
tools. One statistic that would be of interest to researchers is collating and
presenting download figures for authors (rather than by
item/collection/community).
We have encountered problems
separating the item, collection and community statistics within DSpace as all
of their urls are formatted in the same way, we therefore have to query DSpace
data to do this and cannot distinguish them using the statistics data
alone. If the requested item, file,
collection or community is not available in DSpace an error page is returned,
these were being recorded in the same way as successful page which has led to
invalid items being listed in the statistics top ten tables. To prevent this error pages are now recorded
as an error event within Google Analytics.
These changes have given us much
greater understanding of how our repository is being used with the majority of
users coming directly from Google. The
URLrewrite change led to a double of our download statistics as we now capture
users who previously went straight to the download.
Thanks to: Scottish Digital
Library Consortium, Stuart Wood and Gareth Johnson of University of Leicester
for information on the URLrewrite, Graham Triggs formerly of BioMed Central and
now Sympletic.
The code to enable GA stats
within DSpace is freely available from github:
https://github.com/seesmith/Dspace-googleanalytics
You can view our collection and item statistic changes at
http://www.era.lib.ed.ac.uk
Graham Trigg’s slides from
OR2010: http://www.slideshare.net/OpenRepository/enhancing-statistics-google-analytics-and-visualization-apis
Are your repository policies worth the HTML they are written in?
In Neil Stewart's recent guest post on this blog he lamented the The Unfulfilled Promise of Aggregating Institutional Repository Content; in the context of his work with the CORE projects at the Open University Owen Stephens (@ostephens) commented on that post about "technological and policy barriers to a 3rd party aggregating content from UK HE IRs" and has subsequently posted in more detail over on the CORE blog.
Not to put too fine a point on it, I think Owen has identified issues that are fundamental to the potential value of our repository infrastructure in UK HE, at least in terms of responsible 3rd parties building services on top of that infrastructure - though Owen also asks in the title of his post "What does Google do?" for which the short answer is that it indexes (harvests) metadata and full text for (arguably) commercial re-use unless asked not to by robot.txt. This is not necessarily to suggest that Google is irresponsible, it may well be but that is a rather bigger discussion!
For CORE, by comparison, it has understandably been important to establish individual repository policy on re-use of metadata and full text content; where such policies exist at all they are invariably designed to be human readable rather than machine readable which is obviously is not conducive to automated harvest, in spite of guidance being available on how to handle both record, set and repository level rights statements in OAI-PMH from http://www.openarchives.org/OAI/2.0/guidelines-rights.htm.
To quote Owen in his review of policies listed in OpenDOAR he found that "Looking at the 'metadata' policy summaries that OpenDOAR has recorded for these 125 repositories the majority (57) say "Metadata re-use policy explicitly undefined" which seems to sometimes mean OpenDOAR doesn't have a record of a metadata re-use policy, and sometimes seems to mean that OpenDOAR knows that there is no explicit metadata re-use policy defined by the repository. Of the remaining repositories, for a large proportion (47) OpenDOAR records "Metadata re-use permitted for not-for-profit purposes", and for a further 18 "Commercial metadata re-use permitted"."
It might be suggested that machine-readability is actually secondary to what is potentially misconceived policy in the first place - or which hasn't perhaps been fully thought through and at the very least is fatally fragmented across the sector - and that arguably is the result of lip-service rather than based on what actually happens in the real (virtual) world.
For my own part, in my institutional role, I was very, er, green (no pun intended) when I defined our repository policies back in 2008 using the OpenDOAR policy creation toolkit - http://www.opendoar.org/tools/en/policies.php - and to be frank I haven't really revisited them since. I suspect I'm not terribly unusual. To quote Owen once more, "the situation is even less clear for fulltext content than it is for metadata. OpenDOAR lists 54 repositories with the policy summary "Full data item policies explicitly undefined", but after that the next most common (29 repositories) policy summary (as recorded by OpenDOAR) is "Rights vary for the re-use of full data items" - more on this in a moment. OpenDOAR records "Re-use of full data items permitted for not-for-profit purposes" for a further 20 repositories, and then (of particularly interest for CORE) 16 repositories as "Harvesting full data items by robots prohibited".
The (reasonably unrestrictive) metadata and full-text policies I chose at Leeds Metropolitan University state that "the metadata may be re-used in any medium without prior permission for not-for-profit purposes and re-sold commercially provided the OAI Identifier or a link to the original metadata record are given" and "copies of full items generally can be reproduced, displayed or performed, and given to third parties in any format or medium for personal research or study, educational, or not-for-profit purposes without prior permission or charge". Even this, with the word "generally" implicitly recognises the fact that there may be different restrictions that apply to different items which to some extent reflects the complexity of negotiating copyright for green OA, not to mention the other types of records that repositories may hold (e.g. our repository also comprises a collection of Open Educational Resources [OER] which are in fact licensed at the record level with a Creative Commons URI in dc:rights as in this example - http://repository-intralibrary.leedsmet.ac.uk/IntraLibrary-OAI?verb=GetRecord&identifier=oai:com.intralibrary.leedsmet:2711&metadataPrefix=oai_dc)
Nor are my policies available in a machine readable form (which as we've established is typical across the sector) and I'm not actually sure how this could even be achieved without applying a standard license like Creative Commons?
Owen goes on to consider "What does Google do?", if you haven't already it's certainly worth reading the post in full but he concludes that "Google, Google Scholar, and other web search engines do not rely on the repository specific mechanisms to index their content, and do not take any notice of repository policies". Indeed, I think in common with many repository managers, I devote a lot of time and effort on SEO to ensure my repository is effectively indexed by Google et al and that full-text content can be discovered by these global search engines...which seems somewhat perverse when our own parochial mechanisms and fragmented institutional policies make it so difficult to build effective services of our own.
Monday, 19 March 2012
UKCoRR, RSP and DRF - Japan and the UK in Agreement
As you'll have probably seen last week on the lists UKCoRR, in collaboration with the RSP and Japan's DRF (Digital Repository Federation) have signed a memorandum of understanding.
The Memorandum includes a commitment to
You can read more about this, and view the memorandum on the RSP's pages.
- Sharing experience and expertise
- Inviting and possibly sponsoring representatives from partners to participate in RSP and DRF events
- Joint efforts to seek funding and/or support
Obviously from UKCoRR's perspective (and being unfunded as we are) we're mostly about the first option in the agreement; but all the same it's the first time we've signed up to an international agreement and is something that all members can be proud of - the furtherance of recognition of the importance of the repository worker and manager around the world.
Tuesday, 6 March 2012
The Unfulfilled Promise of Aggregating Institutional Repository Content (Guest Post)
Our thanks to Neil Stewart, Digital Repository Manager at City University London for the following guest post which raises some interesting questions for us all.
----
----
A very good question was posed on Stephen Curry’s blog by Björn Brembs recently (Curry and Brembs are a couple of the more prominent figures supporting the Elsevier boycott):
I’ve always wondered why the institutional repositories aren’t working with, e.g. PubMed etc. to make sure a link to their version is displayed with the search results. I mean, how difficult can this be?
This got me thinking, how difficult can it be? Aggregating and re-using institutional repository (IR) content at subject level is, after all, one of the promises of the Green road to Open Access.
The infrastructure is already in place, in the form of the many OAI-PMH compliant institutional repositories out there, and there is also the SWORD client, which allows flexible transfer of repository content. Some examples do exist- for example the Economists Online service, which harvests material from selected economics research-intensive universities, then makes it available via a portal. But (to my knowledge) there has been no work done to provide a way of e.g. ensuring all a repository’s eligible physics content is automatically uploaded to ArXiv, or all biomedical research to UKPMC.
Subject repositories have gained critical mass in certain disciplines (to add to the examples above, see also RePEC for economics, SSRN for social sciences and DBLP for computer science), meaning that if a paper doesn’t appear there, it’s far less visible. This means that the incentive to post locally is greatly reduced- yes, your paper will appear in Google, but a paper in ArXiv will appear both in Google and in the native interface of the repository where everyone else in your discipline is depositing.
So if the infrastructure is there and the rationale to create these links exists, why has it not been happening to any meaningful extent already? I suspect it’s because of the fact that the IR landscape is, by its very nature, a fragmented one. Those with responsibility for IRs (managers, IT people, and senior management) are understandably concerned with local issues: ensuring that IRs are properly managed and integrated with the university’s systems, as well as the usual open access and service awareness-raising and advocacy. Having time to think about the automatic population of ArXiv with papers from your home repository is probably pretty far down one’s to-do list.
That’s not to say that repository managers are oblivious to these issues- but here another problem arises. Few individual repository managers, I would guess, would think that they individually could negotiate with and persuade ArXiv that automatic harvesting of physics content from their repository, and their repository alone, would be worth ArXiv’s while. This is, perhaps, where UKCoRR (or other national bodies- JISC perhaps?) might come in. If ArXiv or similar subject repositories could be persuaded of the merits of harvesting IR content (whether full text or metadata pointing back to IR holdings), it would allow all repositories to plug in to this system, and offer it as a service to academics (two for one deposit- local IR and ArXiv at the same time!)
So, what do people think? Is there any appetite for turning this into a project that UKCoRR members could take forward, perhaps with UKCoRR and/ or JISC oversight? Comments please!
Monday, 27 February 2012
The COAR Question
Those of you whom attended the Portsmouth meeting last month, and hopefully everyone on the list, should be aware of COAR. As you know there have been some very tentative discussions going on behind the scenes relating to the question of should UKCoRR become a member of COAR.
There are a number of obstacles to membership in our way - not least of which is the question of how as a lightweight unfunded organisation we would afford to pay the annual membership fee. There are also broader policy questions about whether membership of COAR would be in the best interests of UKCoRR's long term Independence of action, policy and governance. You only have to glance at the recent announcements from us both on the Elsevier question to see that while the two groups have for the most part allied goals that we are likely to come from two different angles on some issues.
COAR is an organisational membership body funded by subscriptions pushing ahead the interests of open access and repositories. UKCoRR is a individual membership organisation unfunded and independent that pushes forward the representation and development of its members, as well as the role of repositories in the UK. There are other differences but I encourage you all to study the goals of both COAR and UKCoRR and come to your own conclusion on the compatibility or otherwise of the two organisations.
As I said in Portsmouth, as Chair while I can see a certain simpatico in establishing strong lines of communication and liaison with COAR (or indeed any other similar body) I do have a number of concerns over formal membership for UKCoRR.
Not least among these are these questions:
Rather than UKCoRR becoming a member, would it not perhaps be a better idea for our host institutions to become members of COAR (UK membership is currently negligible)? Would this better suit the aims of both organisations, and our employers to boot?
As such I am looking to you the membership to give the Committee a steer on this. Leaving aside the fee question, the core question is: Should UKCoRR explore routes to becoming a formal member of COAR?
Najla Rettberg of COAR has helpfully provided a bit more information from their perspective that I'd encourage you all to read before responding.
I await your thoughts with considerable interest - please feel free to comment here or if you prefer contact myself or any of the Committee offline.
[Update 2/April/2012: As UKCoRR members will know already; following the discussions on the list and inside the Committee it has been decided that membership within COAR is not something that will be pursued. As Chair I've written to COAR to inform them of our decision, and warmly welcomed them to consider entering into a memorandum of understanding and support with us; in much the same way as we have with the RSP and the DRF.]
There are a number of obstacles to membership in our way - not least of which is the question of how as a lightweight unfunded organisation we would afford to pay the annual membership fee. There are also broader policy questions about whether membership of COAR would be in the best interests of UKCoRR's long term Independence of action, policy and governance. You only have to glance at the recent announcements from us both on the Elsevier question to see that while the two groups have for the most part allied goals that we are likely to come from two different angles on some issues.
COAR is an organisational membership body funded by subscriptions pushing ahead the interests of open access and repositories. UKCoRR is a individual membership organisation unfunded and independent that pushes forward the representation and development of its members, as well as the role of repositories in the UK. There are other differences but I encourage you all to study the goals of both COAR and UKCoRR and come to your own conclusion on the compatibility or otherwise of the two organisations.
As I said in Portsmouth, as Chair while I can see a certain simpatico in establishing strong lines of communication and liaison with COAR (or indeed any other similar body) I do have a number of concerns over formal membership for UKCoRR.
Not least among these are these questions:
- What does UKCoRR the organisation really get out of membership?
- What do UKCoRR members get out of our membership?
- How closely does membership tie us to COAR's agenda and policy?
- Is it better to maintain our independence rather than interdependence?
Rather than UKCoRR becoming a member, would it not perhaps be a better idea for our host institutions to become members of COAR (UK membership is currently negligible)? Would this better suit the aims of both organisations, and our employers to boot?
As such I am looking to you the membership to give the Committee a steer on this. Leaving aside the fee question, the core question is: Should UKCoRR explore routes to becoming a formal member of COAR?
Najla Rettberg of COAR has helpfully provided a bit more information from their perspective that I'd encourage you all to read before responding.
I await your thoughts with considerable interest - please feel free to comment here or if you prefer contact myself or any of the Committee offline.
[Update 2/April/2012: As UKCoRR members will know already; following the discussions on the list and inside the Committee it has been decided that membership within COAR is not something that will be pursued. As Chair I've written to COAR to inform them of our decision, and warmly welcomed them to consider entering into a memorandum of understanding and support with us; in much the same way as we have with the RSP and the DRF.]
Friday, 17 February 2012
Elsevier: The Big Bad or Walking with Dinosaurs?
You can't help but have seen in the last few weeks all the press about Elsevier in the blogsphere and news media, especially The Cost of Knowledge Petition. It's been hard to avoid, and it's been a matter of debate within the UKCoRR Community as well. One thing that raised my eyebrows more than their prices was the statement from COAR urging them "...to reconsider its prohibitive approach to open access and revise its policies to allow the deposit of research articles with minimum delay." I think it's a brave move, although one fraught with political issues - coming down so heavily on the "anti" side of the debate.
 UKCoRR certainly feels that the support of such retrograde ideas as the RWA by the AAP, and chief among them Elsevier, is something that has the potential to have significantly deleterious long term effects on the cause of opening access for all to the treasures of human knowledge. As the Big Bad (it seems) for the RWA, we are not at all surprised that they are now reaping the whirlwind. Not to mention their continued muddying of the authors licenses and permissions which causes each and everyone of us a headache I'm quite sure. But they are not the only publisher to be guilty of these sins against open access, and part of me feels that singling them out for such a public barracking perhaps might let other issues or publishers slip back into the shadows. I think we all need to remain vigilant and sound the alarm just as loudly should any other organisation or stakeholder in the scholarly publishing domain make such similar policy moves.
One thing UKCoRR has striven to do from our very earliest days is attempt to engage with publishers, along with other stakeholders, to seek a joined up future of scholarly communication. To date I will confess these giants in the playground have ignored the minnows in the corner (from their perspective at least). However, one only needs to point to the lessons of history and perhaps remind them that the massive and preeminent lifeforms that were the dinosaurs were once as all dominant while tiny rodents scampered around their feet. When the sea change came in the shape of the K-T extinction event the dinosaurs were so locked into their evolutionary niche that they were unable to adapt, and their successors rose from beneath their claws.
 Is open access the world killer for the publishing dinosaurs? Personally I hope not, but seeing this increasing reactionary inflexibility from the big boys of publishing does certainly ring one or two points of commonality in my head. The more they dig into their 19th/20th Century position as gatekeepers, guardians and protectors of the IP of the scholars of the world, and the more the 21st Century makes it easier, faster and simpler for others to fill the various roles, the more I think they're going to back themselves down into their very own Chicxulub crater.
But it also means that we in the repository sector have to remain just as agile if we are to survived the impact. I often say to my team that what we do and how we work with repositories today is very much evolved from where we were when I entered the field in 2006. We've been evolving, and we need to keep evolving if we are to meet the needs of our academics as they, hopefully, finally wise us to the fact that they don't need publishers like they used to; and that the apparatus and expertise to help them share, curate and celebrate their knowledge output is just a short walk across the campus to the repository office.
One thing I would charge all UKCoRR members with is going through the signatories on the petition to see if they can find any local authors and academics. It is without a doubt a golden opportunity to make use of these self-declared opponents of restrictive knowledge exchange paradigms. These fine people are willing to speak out, and up, about open access and should be approached as potential local champions of the cause. Cherish them, support them and above all make use of their insights from the academic perspective; because I often sense that we repository workers don't always quite manage to chime to right bells for academics.
As some UKCoRR members have said to me - the press visibility in the academic sphere over the restrictions that publishers make on access to our shared knowledge has never been higher. If nothing else the Cost of Knowledge row is not going to go away quickly, and there will be more than a handful of previously unaware and perhaps uncaring academics who can be brought into the open access fold and the light of a new, better, more open tomorrow.

One thing UKCoRR has striven to do from our very earliest days is attempt to engage with publishers, along with other stakeholders, to seek a joined up future of scholarly communication. To date I will confess these giants in the playground have ignored the minnows in the corner (from their perspective at least). However, one only needs to point to the lessons of history and perhaps remind them that the massive and preeminent lifeforms that were the dinosaurs were once as all dominant while tiny rodents scampered around their feet. When the sea change came in the shape of the K-T extinction event the dinosaurs were so locked into their evolutionary niche that they were unable to adapt, and their successors rose from beneath their claws.
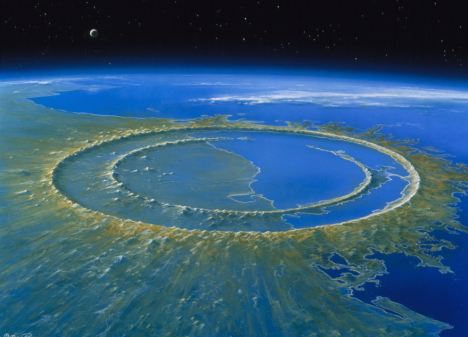
But it also means that we in the repository sector have to remain just as agile if we are to survived the impact. I often say to my team that what we do and how we work with repositories today is very much evolved from where we were when I entered the field in 2006. We've been evolving, and we need to keep evolving if we are to meet the needs of our academics as they, hopefully, finally wise us to the fact that they don't need publishers like they used to; and that the apparatus and expertise to help them share, curate and celebrate their knowledge output is just a short walk across the campus to the repository office.
One thing I would charge all UKCoRR members with is going through the signatories on the petition to see if they can find any local authors and academics. It is without a doubt a golden opportunity to make use of these self-declared opponents of restrictive knowledge exchange paradigms. These fine people are willing to speak out, and up, about open access and should be approached as potential local champions of the cause. Cherish them, support them and above all make use of their insights from the academic perspective; because I often sense that we repository workers don't always quite manage to chime to right bells for academics.
As some UKCoRR members have said to me - the press visibility in the academic sphere over the restrictions that publishers make on access to our shared knowledge has never been higher. If nothing else the Cost of Knowledge row is not going to go away quickly, and there will be more than a handful of previously unaware and perhaps uncaring academics who can be brought into the open access fold and the light of a new, better, more open tomorrow.
Subscribe to:
Posts (Atom)